What Is Tokenization? Why AI Reads in Pieces
How AI breaks your words into tokens, and why it matters for cost and quality. A simple explainer with real examples.
In this article
What is Tokenization in AI? Why AI Reads in Chunks & Cost Impact
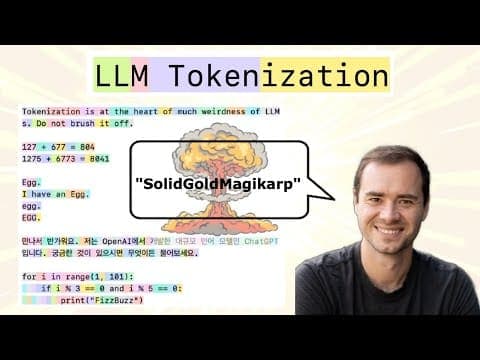
Full concept explanation and architecture deep-dive. Watch while reading or jump into specific chapters.
1. Why AI Can't Read Words Directly
Computers cannot calculate probability distributions over infinite raw strings. If you assigned a unique ID to every single word in human history, your model vocabulary would need tens of millions of entries, failing every time a user coined a new slang word, typo, or username.
Conversely, if you fed the model individual letters (character-level tokenization), the sequences would become ten times longer, causing compute costs and attention mechanism complexity (O(N²)) to skyrocket.
Tokenization strikes the perfect engineering balance: it breaks text into subword units. Common words become a single token ("apple"), while rare or complex words are split into known subcomponents ("un" + "pre" + "dict" + "able").
2. Byte-Pair Encoding (BPE) Explained
Most state-of-the-art models (including GPT-4, Llama 3, and Mistral) use an algorithm called Byte-Pair Encoding (BPE).
Here is the intuition:
- 1Start with individual bytes or characters as vocabulary.
- 2Scan the training corpus and find the most frequently occurring adjacent pair of characters (e.g. 't' and 'h').
- 3Merge them into a new single token: 'th'.
- 4Repeat this merge step tens of thousands of times.
Over time, frequent sequences like 'ing', 'tion', 'the', and 'const' become individual tokens. Modern tokenizer vocabularies typically contain between 32,000 and 128,000 unique token IDs.
3. Characters vs Words vs Tokens: The Math
As an engineering rule of thumb for standard English:
- 1 token ≈ 4 characters
- 1 token ≈ 0.75 words
- 100 tokens ≈ 75 words
- 1,000 words ≈ 1,333 tokens
However, code and formatting behave differently. Indentation spaces, JSON brackets, and camelCase identifiers split into separate tokens unless specifically optimized by the tokenizer dictionary.
4. How Tokenization Impacts Cost & Latency
Every major AI API provider (OpenAI, Anthropic, Google, Together.ai) bills on input and output tokens:
- Prompt tokens: What you send into the model.
- Completion tokens: What the model streams back.
Because transformer inference generates completion tokens sequentially one-by-one, your API response latency is directly proportional to output token count, NOT prompt length. Minimizing verbose output instructions reduces both your AWS/OpenAI bill and your user waiting time.
Instruct the model to reply concisely or return structured JSON schemas. Generating 100 tokens takes 1/4 the time and cost of generating 400 tokens of conversational filler.
5. The Multilingual Token Tax
Because early tokenizers were trained predominantly on English web text, non-Latin scripts (Arabic, Urdu, Hindi, Japanese) were frequently split into 3 to 6 tokens per single word.
This created a "token tax" where non-English users consumed their context window and API budgets 3x faster. Modern tokenizers like GPT-4o and Llama 3 expanded their vocabulary to 128K+ tokens, drastically improving compression for global languages and source code.
Mastering tokenization is the key to mastering AI operational costs, prompt caching, and low-latency production pipelines.
Written by Anus Imran
FounderAnus builds autonomous AI agents, enterprise web applications, and production systems at CODELOSET. He breaks down technology and architectures every week on YouTube.
Continue Exploring Technical Insights
AI vs Machine Learning vs Deep Learning: What's the Difference?
A plain-English map of the terms everyone mixes up. No jargon, no maths — just a clear explanation of how these three ideas relate to each other.
Want to Deploy This Architecture in Your Business?
Talk directly to Anus Imran. We audit your operational friction and design custom autonomous AI systems, web apps, and data workflows tailored specifically for your team.
30 minutes · Direct engineer conversation · No sales pressure