What Is an LLM? How ChatGPT-Style Models Actually Work
The idea behind large language models, without the maths. What they are, how they learn, and why they can do things that look surprisingly intelligent.
In this article
How Large Language Models (LLMs) Actually Work Without the Maths
Full concept explanation and architecture deep-dive. Watch while reading or jump into specific chapters.
1. The Ultra-Advanced Autocomplete Analogy
At its core, a Large Language Model is an astronomical probability engine trained on one single objective:
"Given the preceding sequence of words (tokens), what is the most statistically plausible next token?"
When you type "The cat sat on the...", the model does not consult an encyclopedic database of felines. Instead, its billions of neural weights evaluate probability distributions across its vocabulary:
- "mat" (62%)
- "rug" (18%)
- "floor" (12%)
- "refrigerator" (0.001%)
By repeating this prediction token by token — thousands of times per second — coherent sentences, complex Python code, and nuanced business analyses emerge organically.
2. The 3 Pillars: Pre-training, Weights, and Embeddings
How does an autocomplete become capable of passing the Uniform Bar Exam? Through three distinct stages:
- 1Pre-training (Unsupervised Reading): The model reads trillions of tokens from Common Crawl, books, academic papers, and GitHub. It adjusts hundreds of billions of numerical connection weights to capture grammar, reasoning patterns, and cultural knowledge.
- 2Instruction Fine-Tuning (SFT): Pre-trained models just continue text (e.g. asking "How do I make tea?" might result in the model generating another question like "How do I make coffee?"). Fine-tuning trains it to behave like a helpful conversational assistant.
- 3RLHF (Reinforcement Learning from Human Feedback): Human evaluators score model answers, penalizing toxicity and rewarding accuracy, clarity, and safety.
3. Why Context Windows & Tokens Matter
An LLM has zero permanent memory between sessions. Every time you submit a prompt, the model reads the entire chat history sent in that payload.
The "Context Window" is the working memory limit (e.g. 128K tokens in GPT-4o, 1M+ tokens in Gemini 1.5). If your conversation exceeds this limit, earlier messages fall out of the model's awareness entirely.
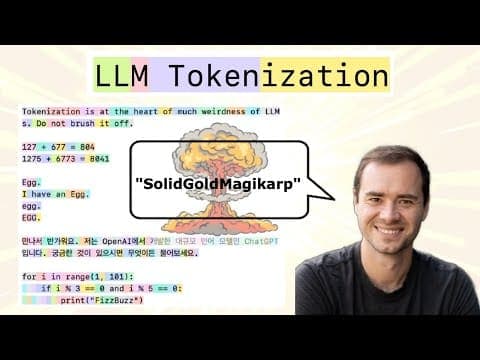
Furthermore, LLMs do not read letters or words — they read tokens (roughly 4 characters or 0.75 words in English). This is why pricing, latency, and throughput in AI engineering are always measured per 1,000 or 1,000,000 tokens.
4. The Truth About Hallucinations
Why do LLMs confidently invent court cases, nonexistent books, or fake API endpoints?
Because LLMs are trained to prioritize plausibility over veracity. If the model does not have factual knowledge about an obscure topic, its weights will generate words that sound stylistically perfect and linguistically convincing, regardless of whether they match physical reality.
Hallucinations are not a bug — they are the very mechanism of creative generation. The engineering challenge is bounding that creativity when facts are non-negotiable.
A foundation model has no awareness of your internal company spreadsheets, inventory numbers, or private CRM records. You must supply that data dynamically.
5. Production Architecture: Grounding with RAG
In production systems built by CODELOSET, we never let an LLM guess. We use Retrieval-Augmented Generation (RAG):
- 1The user asks a question (e.g. "What is our refund policy on damaged shipments?").
- 2Our backend runs a vector similarity search across your company's indexed internal knowledge base.
- 3We extract the exact paragraphs containing the truth.
- 4We inject those paragraphs into the system prompt: "Answer the user question using ONLY the provided facts. If not found, say you do not know."
This eliminates 99% of hallucinations and turns generic generative models into reliable enterprise workhorses.
LLMs are extraordinary probabilistic reasoning engines. When paired with structured databases and deterministic guardrails, they transform entire company workflows.
Written by Anus Imran
FounderAnus builds autonomous AI agents, enterprise web applications, and production systems at CODELOSET. He breaks down technology and architectures every week on YouTube.
Continue Exploring Technical Insights
AI vs Machine Learning vs Deep Learning: What's the Difference?
A plain-English map of the terms everyone mixes up. No jargon, no maths — just a clear explanation of how these three ideas relate to each other.
Want to Deploy This Architecture in Your Business?
Talk directly to Anus Imran. We audit your operational friction and design custom autonomous AI systems, web apps, and data workflows tailored specifically for your team.
30 minutes · Direct engineer conversation · No sales pressure